CUDA Lock-In on Trial After Anthropic's Three-Day AMD Port
Anthropic says an in-house model ported Claude to AMD GPUs in three days. We audit the CUDA lock-in math and give you a rule for your GPU plans.
Source feed
2449 items
The world's AI knowledge in one place. AI RSS feed aggregator monitoring OpenAI, Anthropic, Google AI, Meta, Hugging Face. Tutorials, news, and insights — as they happen.
Anthropic says an in-house model ported Claude to AMD GPUs in three days. We audit the CUDA lock-in math and give you a rule for your GPU plans.
At 12,000 employees, AI Ghodsi is the first to admit that he can't know everyone and that they are unlikely to confess the things that go wrong to him. But he doesn't need them to. He uses Databricks' newly revised Genie agent for that.
A palace-hotel wedding week shows where assistants, copilots, agents, and orchestration fit, and why Gartner expects 40%+ of agentic AI projects to be cancelled.
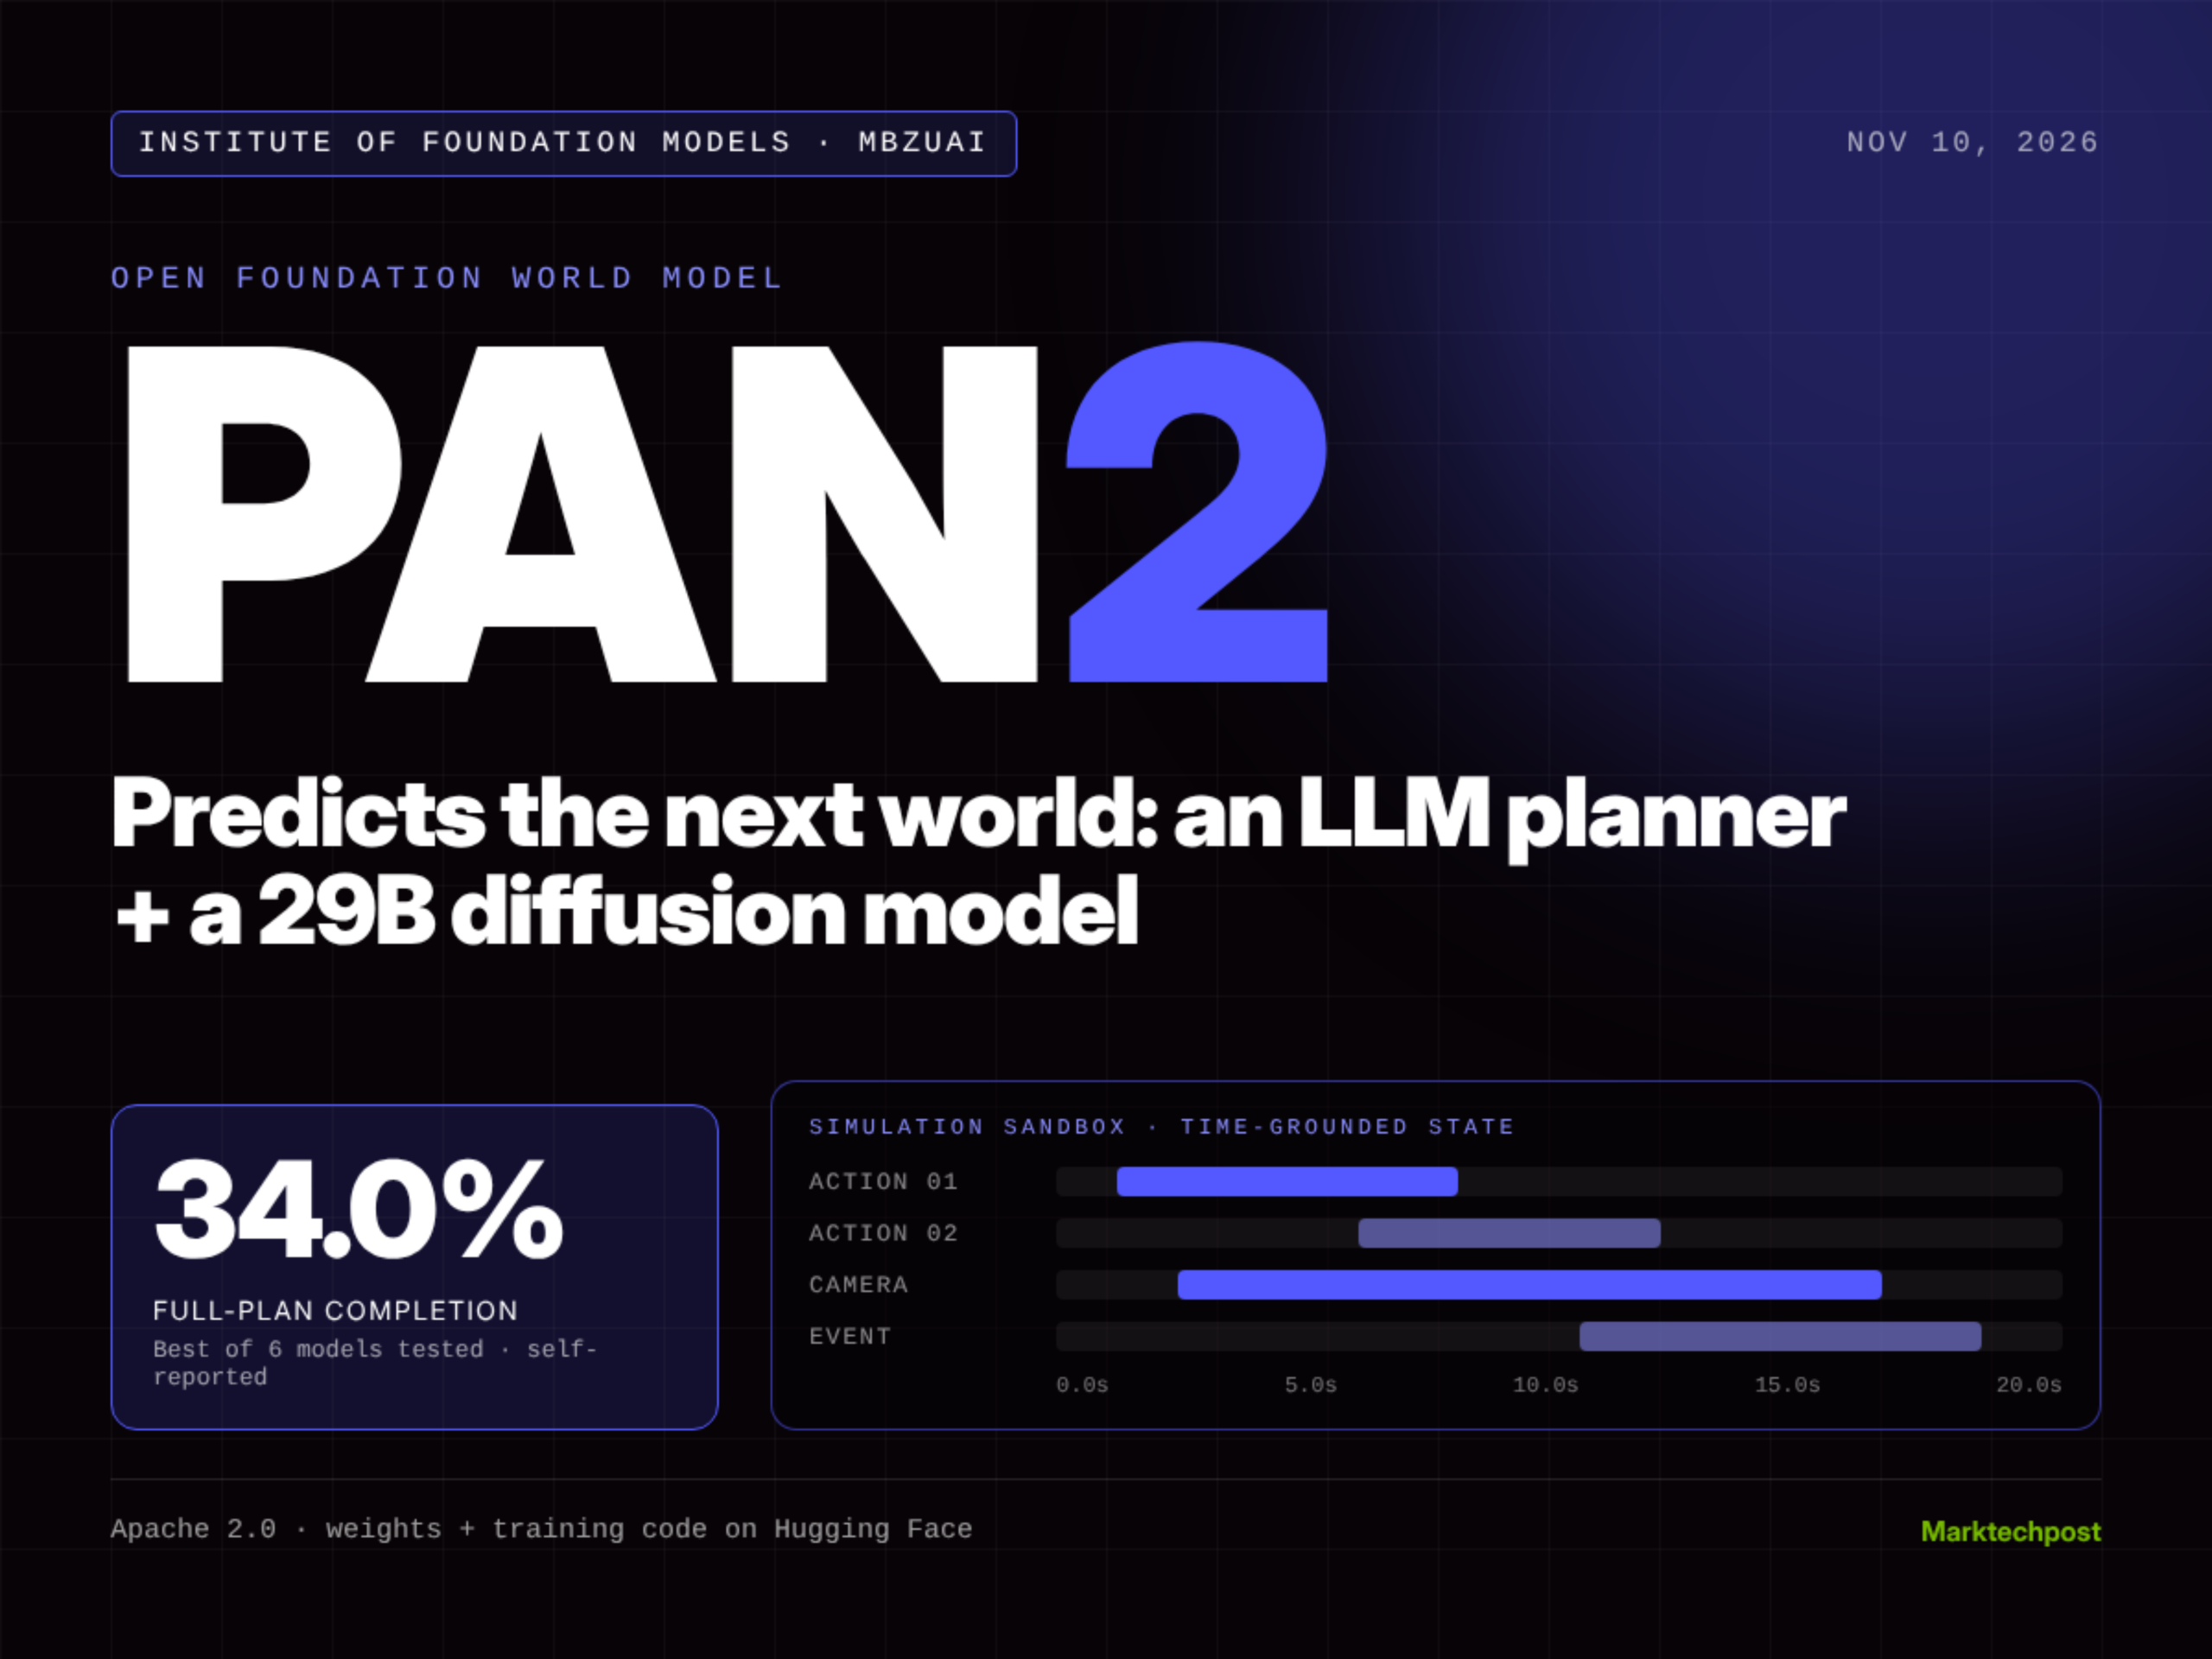
PAN 2 is MBZUAI's open world model: 29B parameters, Apache 2.0, up to 20 seconds of video. It completes 34% of multi-step plans on IFM's own test.
Google previewed /swarm in Antigravity on Nov 10, 2026: a coordinator, named workers and a verifier on one shared board. Plans, limits and what is missing.
Entities: GoogleGoogle Antigravity
CellCog's Agent Max and Creative Max tiers moved to Claude Fable 5.2 on November 11, 2026. Every other tier stays on Opus 5.5. What changes for you.
Entities: ClaudeClaude Fable
A Sate Padang vision test and a Malaysia capital question show why the free, private model needs grounding and validation before it leaves prototyping.
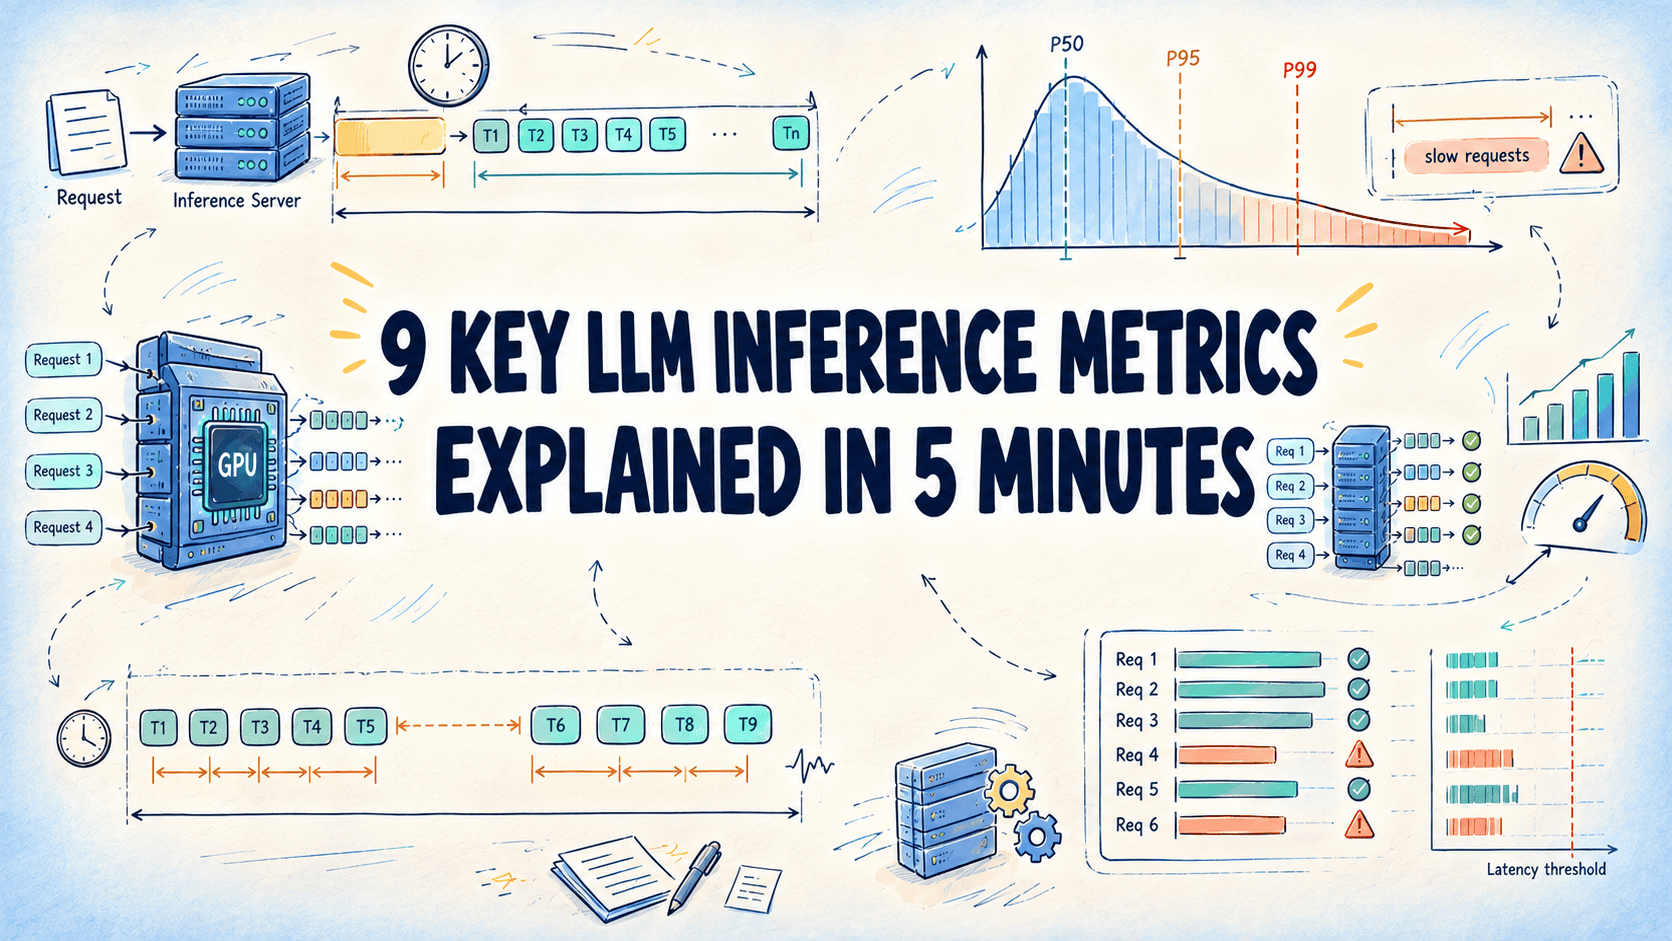
Learn how to measure LLM inference performance using key metrics and formulas for latency, token generation speed, and system load.
Trained on six PathMNIST tissues with a small KEEP adapter, it handled added labels without retraining, though a linear classifier hit 88% on familiar ones.
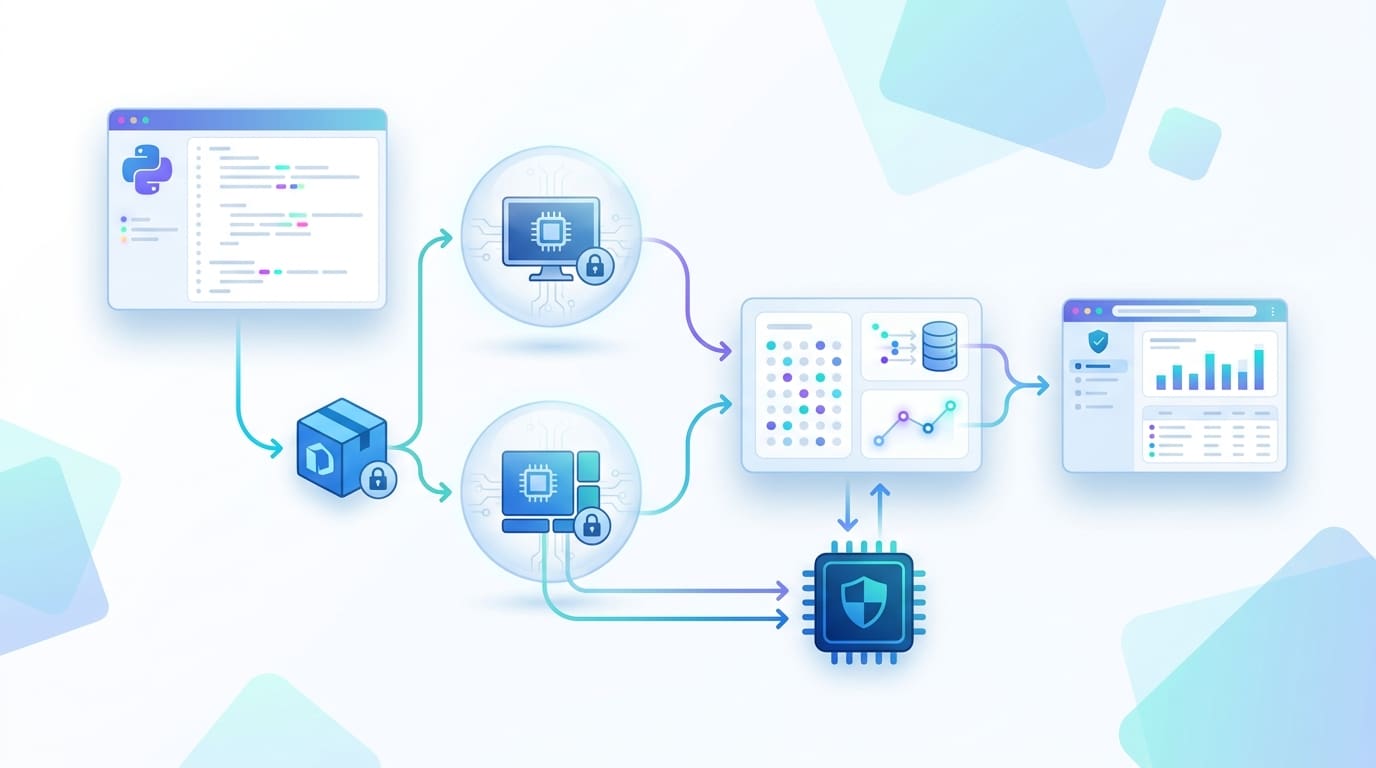
In this article, you will learn how to sandbox the code an AI agent writes by running it in a limited subprocess, a hardened Docker container, and a Firecracker microVM, and how to compare their safety and latency.
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
PAN 2 world model from MBZUAI pairs an LLM planner with a 29B diffusion transformer, under Apache 2.0. PAN 2 world model new release