9 Key LLM Inference Metrics Explained in 5 Minutes
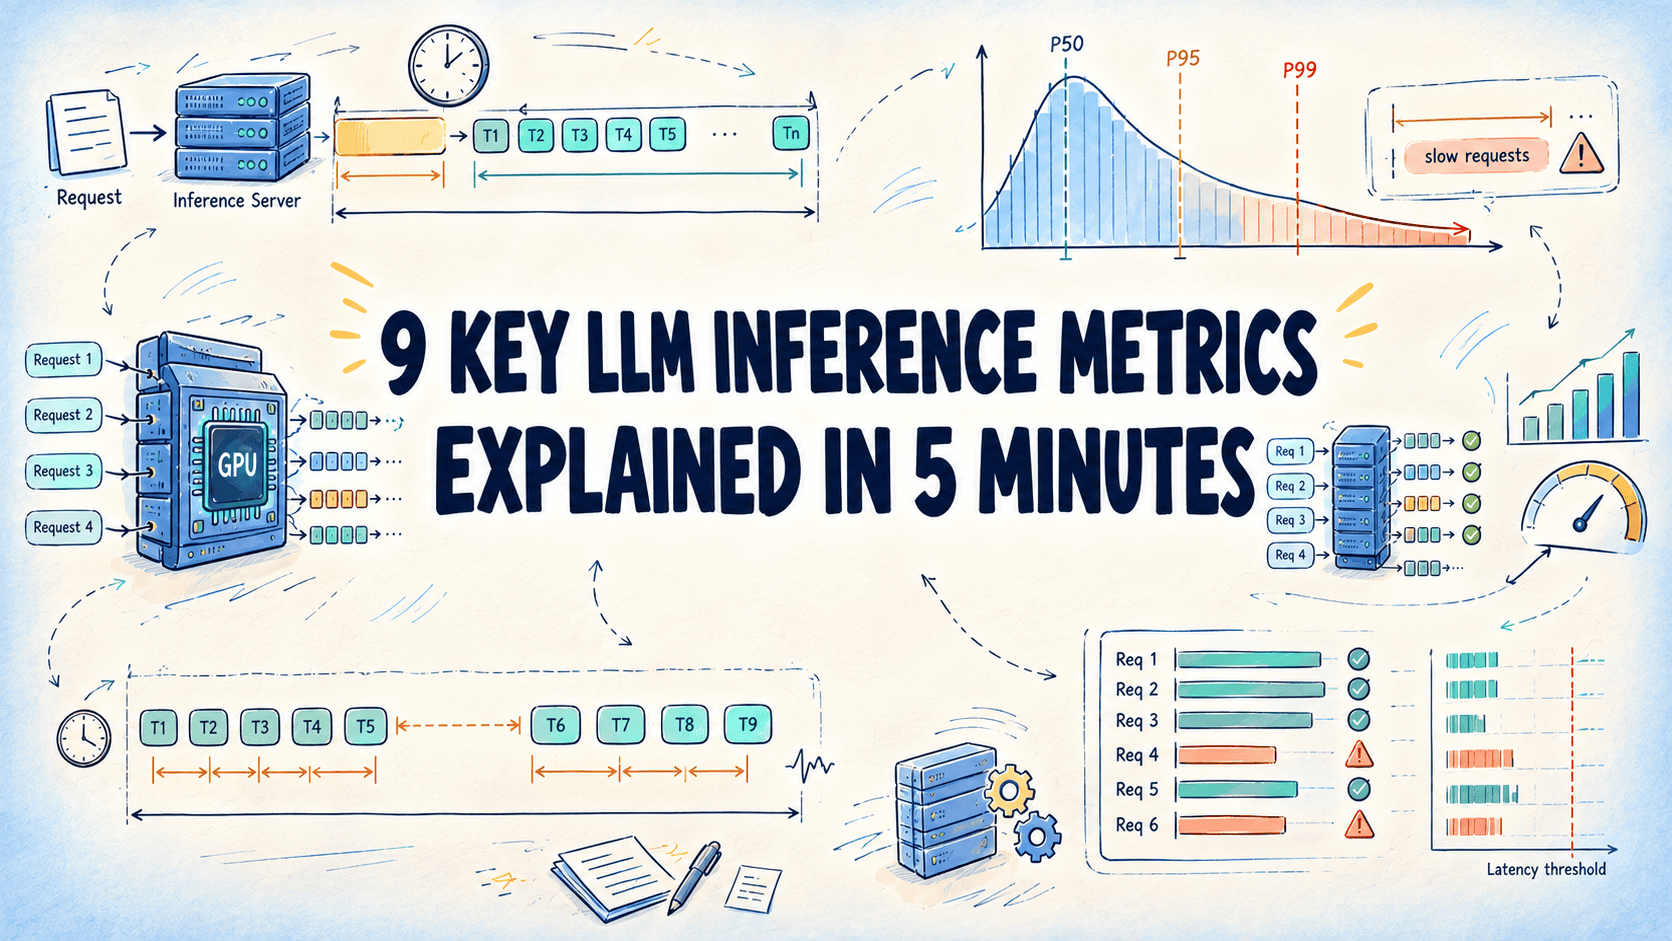
Learn how to measure LLM inference performance using key metrics and formulas for latency, token generation speed, and system load.
KDnuggets · https://www.facebook.com/kdnuggets · https://www.facebook.com/kdnuggets