 Planet AI Developer Filter
Release b12407: model : metal : workaround fusion for LFM3 (#32296) · ggml-org/llama.cpp
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
Source feed
2449 items
The world's AI knowledge in one place. AI RSS feed aggregator monitoring OpenAI, Anthropic, Google AI, Meta, Hugging Face. Tutorials, news, and insights — as they happen.
Planet AI Developer Filter
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
Planet AI Developer Filter
LLM integration plugin for other plugins to depend on
Planet AI Developer Filter
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
Planet AI Developer Filter
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
Planet AI Developer Filter
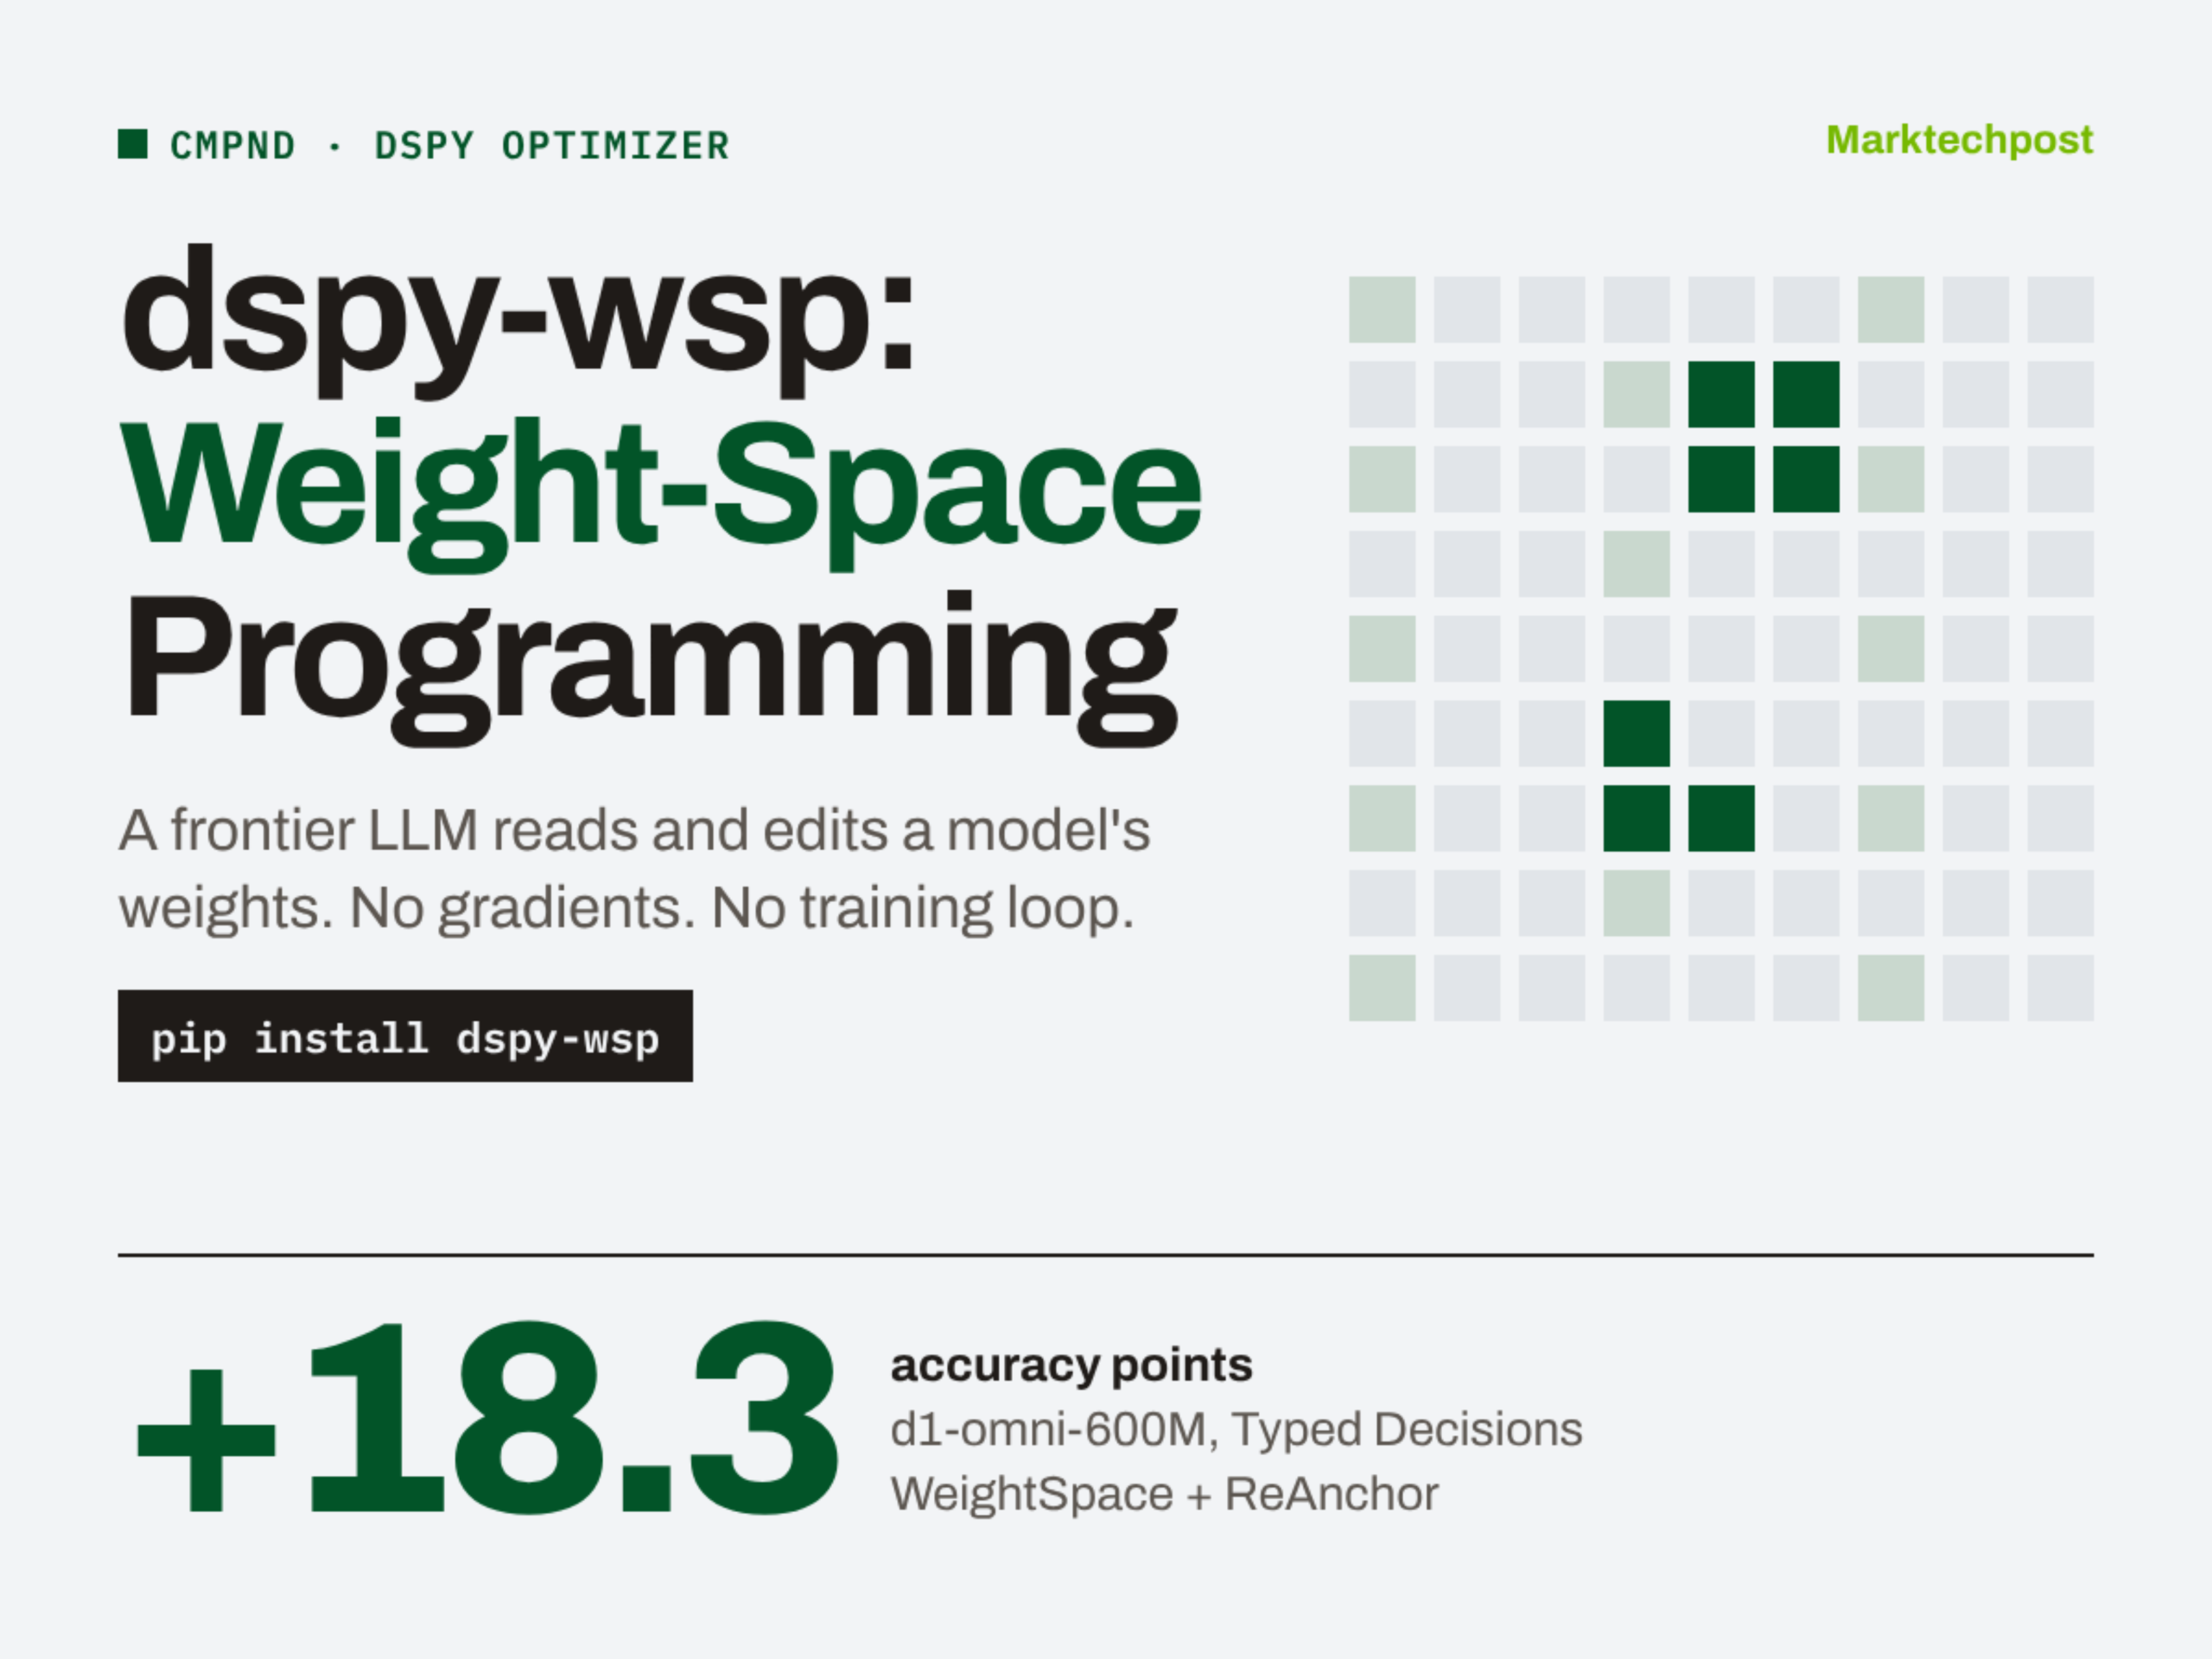
Cmpnd’s dspy-wsp brings weight-space programming to DSPy, letting GPT-6-Astra edit weights directly and lift d1-omni-600M accuracy
Planet AI Developer Filter
During autoregressive decoding, a transformer reads its weights for every new token. At small batch sizes, moving these weights can take more time than computation. Quantization reduces this cost by storing weights with fewer bits. For example, an INT8...

Planet AI Developer Filter
A Reason Machines co-founder says its harness costs up to 20x less. Its own posts say 22% less per solved task than Codex. What each number measures.
Topics: Code Assistants
Entities: Code Assistants
Planet AI Developer Filter
LLM inference in C/C++. Contribute to ggml-org/llama.cpp development by creating an account on GitHub.
Planet AI Developer Filter
LlamaIndex is the document processing platform for AI - Release v0.14.26 · run-llama/llama_index

Planet AI Developer Filter
LangChain now claims 7,000 customers of its model and platform agnostic agent management tool LangSmith.
Planet AI Developer Filter
Amazon Bedrock provides built-in, zero-instrumentation cost attribution that traces every inference call back to the IAM principal that made it. This post shows how to attribute per-user Bedrock costs for AI developer and productivity tools using IAM...
Planet AI Developer Filter
Amazon SageMaker HyperPod Data Capture records live inference inputs and outputs to Amazon S3. This post walks through one end-to-end example: capturing a support router's production traffic, surfacing a new-product blind spot with Amazon Athena,...