
OpenAI AI Coding Filter
Lessons learned on language model safety and misuse
We describe our latest thinking in the hope of helping other AI developers address safety and misuse of deployed models.
OpenAI AI Coding Filter
We describe our latest thinking in the hope of helping other AI developers address safety and misuse of deployed models.
OpenAI AI Coding Filter
We’ve trained language models that are much better at following user intentions than GPT-3 while also making them more truthful and less toxic, using techniques developed through our alignment research. These InstructGPT models, which are trained with...

OpenAI AI Coding Filter
We are introducing embeddings, a new endpoint in the OpenAI API that makes it easy to perform natural language and code tasks like semantic search, clustering, topic modeling, and classification.
Entities: OpenAIOpenAI API
OpenAI AI Coding Filter
Wider availability made possible by safety progress.
Entities: OpenAI

OpenAI AI Coding Filter
We’ve created an improved version of OpenAI Codex, our AI system that translates natural language to code, and we are releasing it through our API in private beta starting today.
Topics: Code Assistants
Entities: OpenAICode AssistantsOpenAI Codex
OpenAI AI Coding Filter
Over 300 applications are delivering GPT-3–powered search, conversation, text completion, and other advanced AI features through our API.

OpenAI AI Coding Filter
We’re releasing an API for accessing new AI models developed by OpenAI.
Entities: OpenAIOpenAI API
OpenAI AI Coding Filter
We’ve contributed to a multi-stakeholder report by 58 co-authors at 30 organizations, including the Centre for the Future of Intelligence, Mila, Schwartz Reisman Institute for Technology and Society, Center for Advanced Study in the Behavioral Sciences, and...

OpenAI AI Coding Filter
We’re releasing Procgen Benchmark, 16 simple-to-use procedurally-generated environments which provide a direct measure of how quickly a reinforcement learning agent learns generalizable skills.

OpenAI AI Coding Filter
As the final model release of GPT-2’s staged release, we’re releasing the largest version (1.5B parameters) of GPT-2 along with code and model weights to facilitate detection of outputs of GPT-2 models. While there have been larger language models released...
OpenAI AI Coding Filter
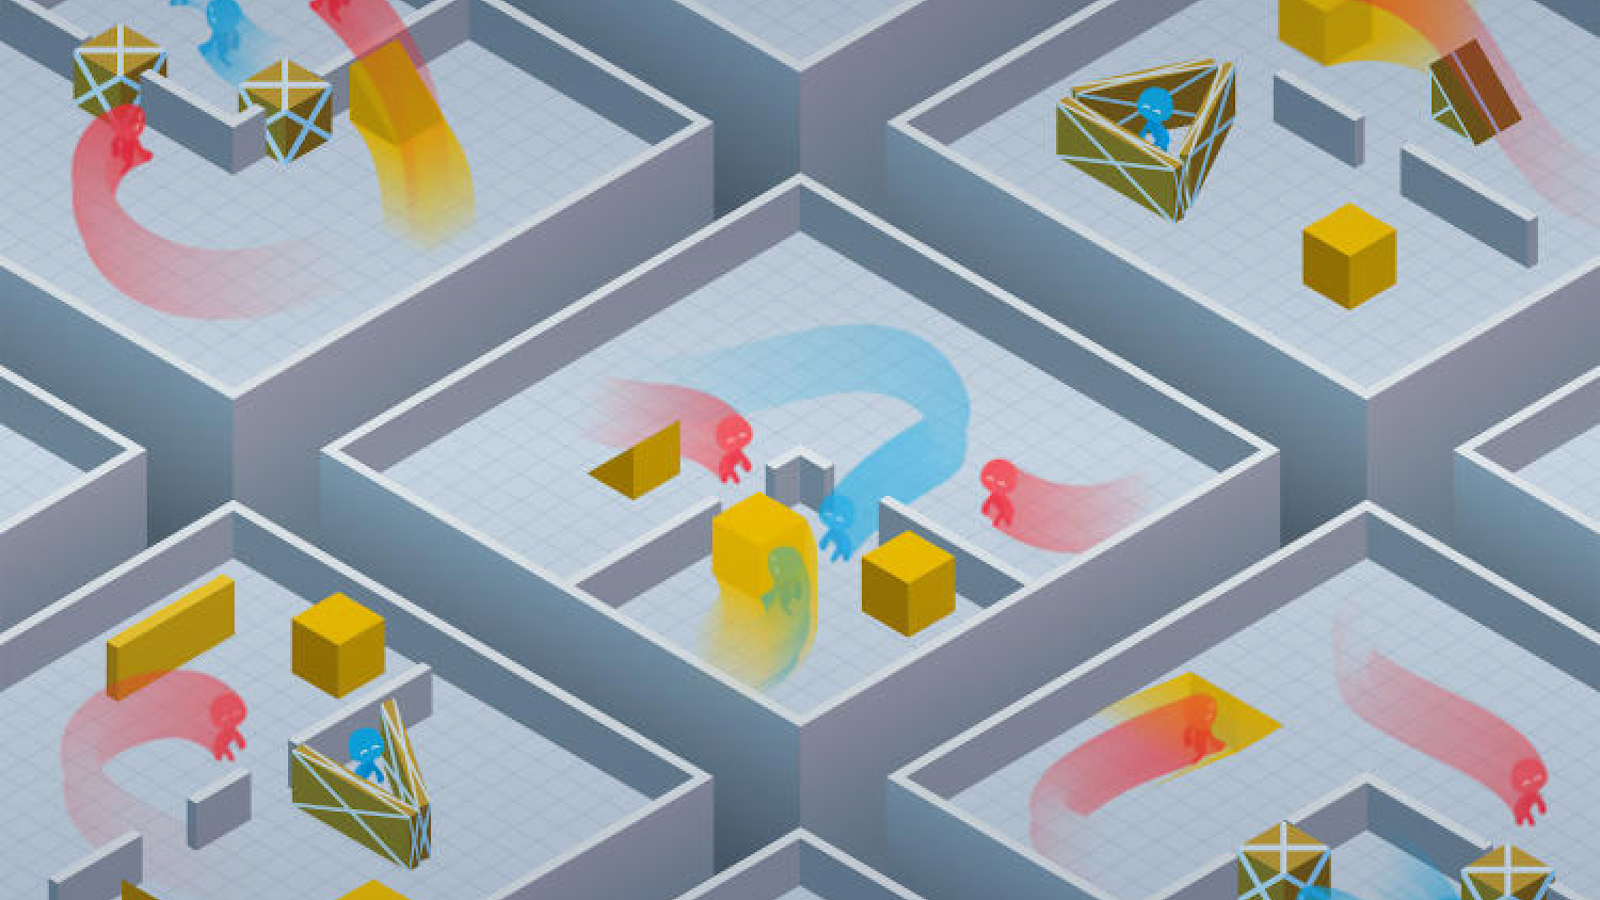
We’ve observed agents discovering progressively more complex tool use while playing a simple game of hide-and-seek. Through training in our new simulated hide-and-seek environment, agents build a series of six distinct strategies and counterstrategies, some...
OpenAI AI Coding Filter
We’ve developed a method to assess whether a neural network classifier can reliably defend against adversarial attacks not seen during training. Our method yields a new metric, UAR (Unforeseen Attack Robustness), which evaluates the robustness of a single...
Topics: Developer Automation
Entities: Developer Automation