Building a High-Performance and Portable vLLM Linear Backend with Helion – PyTorch
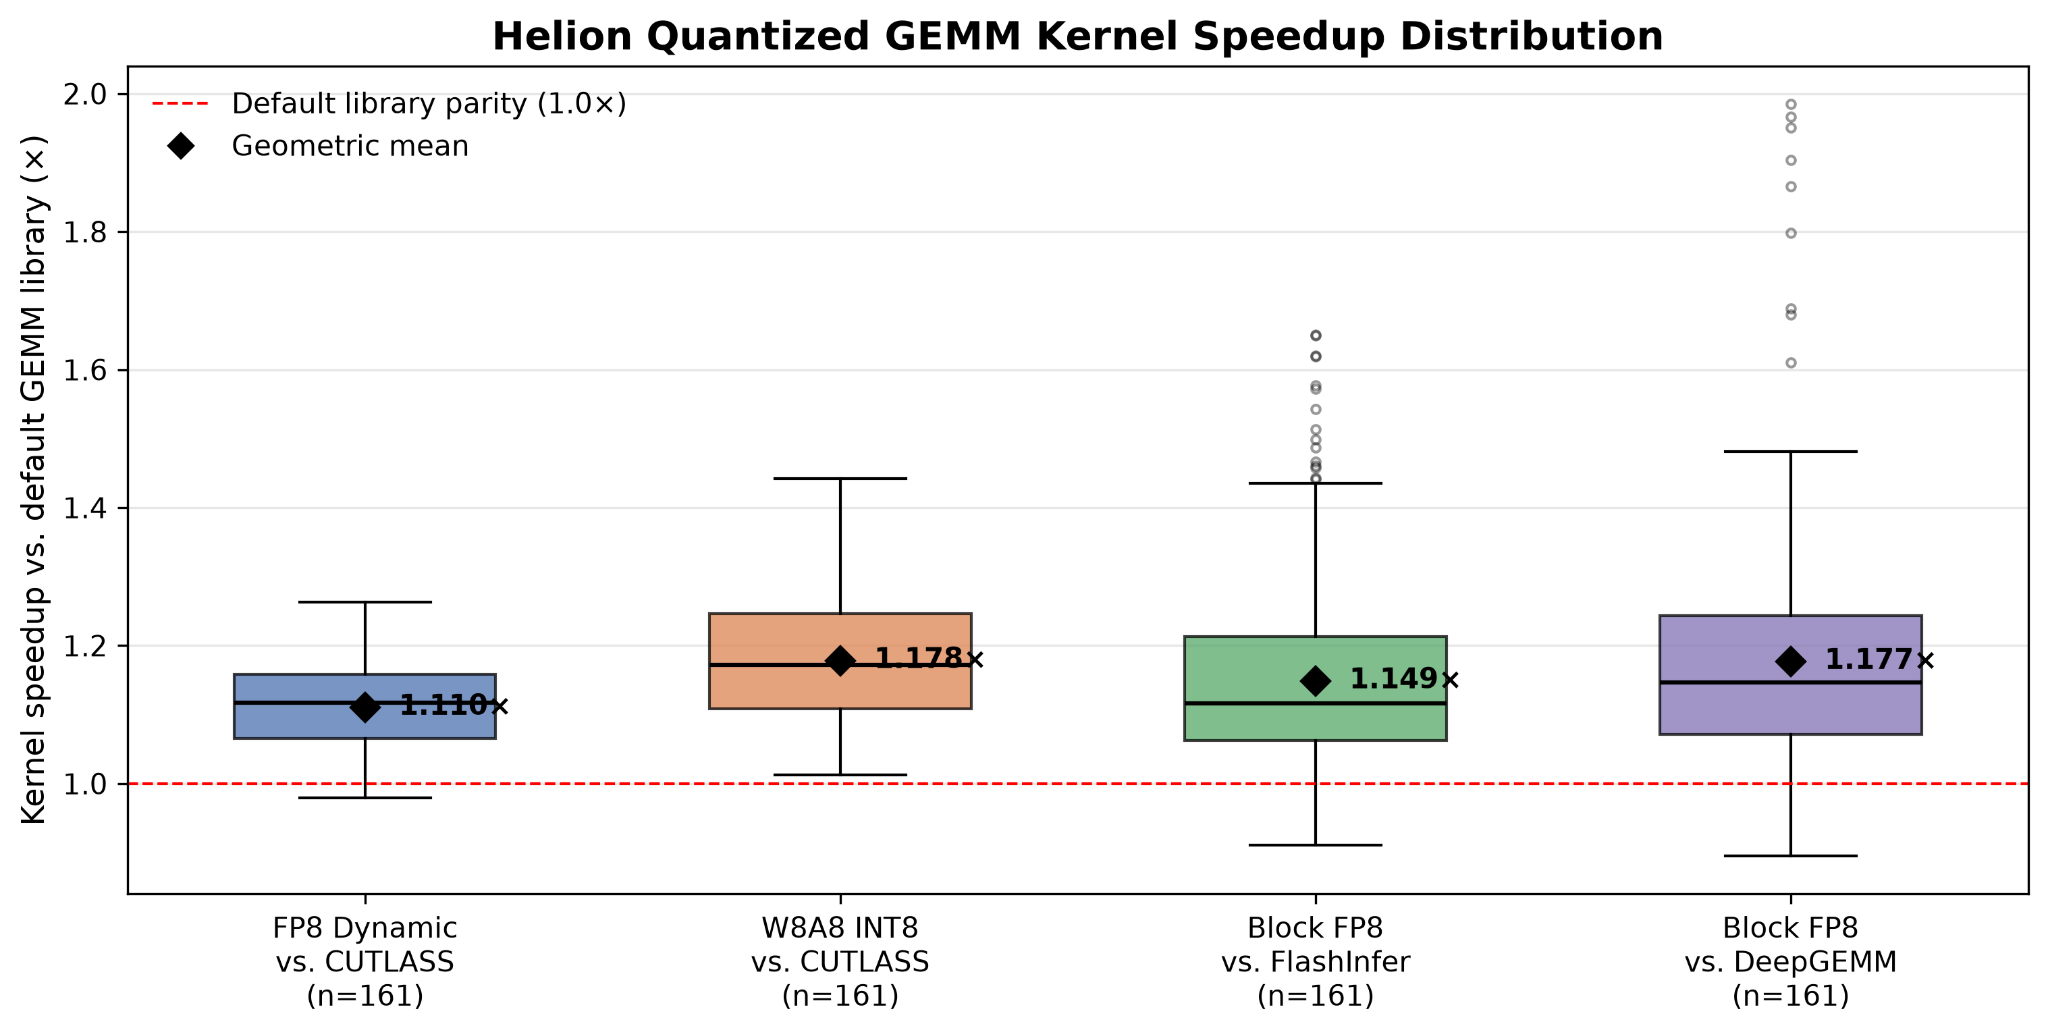
We integrated Helion into vLLM’s linear backend to explore how an autotuned, high-level kernel DSL can improve LLM inference performance while reducing kernel implementation complexity. A single Helion general matrix multiplication (GEMM) implementation can cover multiple algorithmic variants, including Standard GEMM, Split-K, and Swap-AB, with the best variant and config automatically selected through per-shape autotuning.