One Model Family, Two Gold-Level Results: Fine-Tuning Nemotron for IOI and IMO
A Blog post by NVIDIA on Hugging Face
Entities: NVIDIA
Company
A Blog post by NVIDIA on Hugging Face
Entities: NVIDIA
Claude Code at NVIDIA's Free Model Catalog. It Took a Proxy and Four Traps. Claude Code only speaks Anthropic's Messages API. NVIDI...
Topics: Code Assistants
Comprehensive, up-to-date news coverage, aggregated from sources all over the world by Google News.
Topics: Coding Agents
Entities: Coding AgentsNVIDIAGoogle
OpenAI rules out a 2026 IPO while Anthropic promises permanent outside evaluators and reportedly seeks Nvidia's backing for its flotation. Our argument: product builders should judge safety commitments by the independent scrutiny and commercial constraints...
Topics: Developer Automation
New CrowdStrike SafeMind agentic cybersecurity system built with NVIDIA Nemotron open models delivers greater protection and cost savings for cyber defense.
Entities: NVIDIA
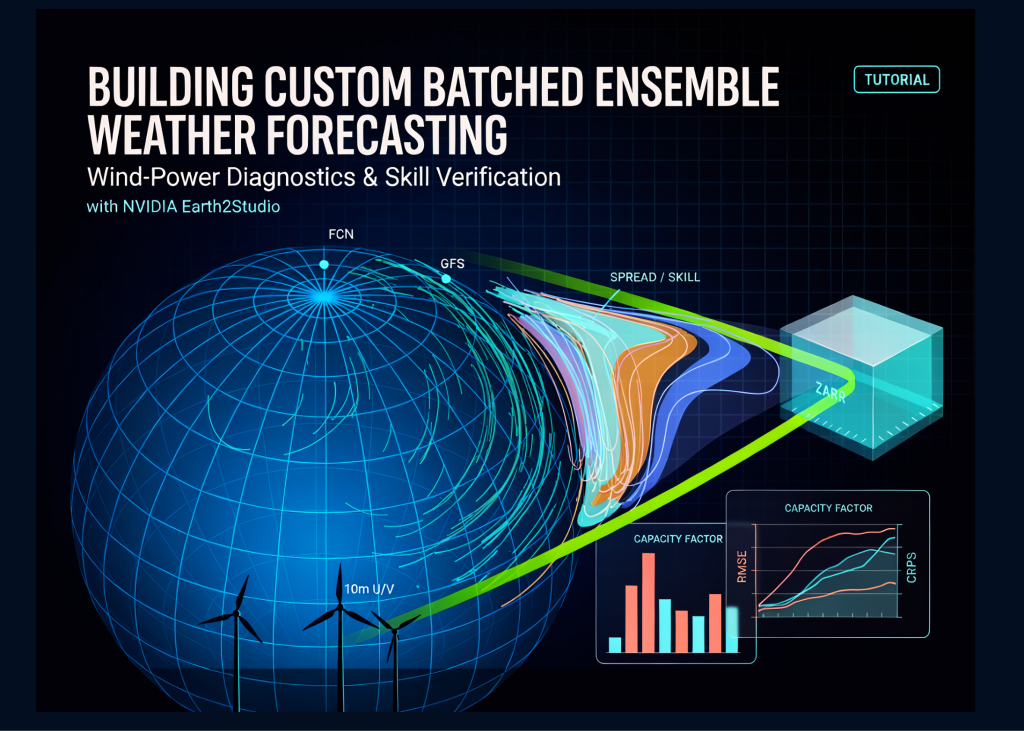
Build custom batched ensemble weather forecasting workflows, implement wind-power diagnostics, using NVIDIA Earth2Studio.
Entities: NVIDIA
Open AI models are evolving faster than ever, but bringing them into native applications can still require model-specific conversion, preprocessing…
Entities: NVIDIA
Cursor's MoK Delivers a 2.37x Performance Improvement on NVIDIA GB300 NVL72 KuCoin
Topics: IDEs
Experiment with Qwen3.8-Flash-Next on NVIDIA GB300 NVL72 for Agentic Coding | NVIDIA Technical Blog NVIDIA Developer
Topics: Coding Agents
Entities: Coding AgentsNVIDIANVIDIA TechnicalNVIDIA Technical BlogNVIDIA DeveloperNVIDIA Technical Blog NVIDIANVIDIA Technical Blog NVIDIA DeveloperNVIDIA GB300NVIDIA GB300 NVL72
Alibaba released the model weights for Qwen3.8-Flash-Next as a preview of the upcoming Qwen4 architecture for developers to experiment with and evaluate.
Topics: Coding Agents
Alibaba released the model weights for Qwen3.8-Flash-Next as a preview of the upcoming Qwen4 architecture for developers to experiment with and evaluate.
Topics: Coding Agents
When an LLM engine process fails, the standard recovery path involves a cold restart. This requires loading weights into HBM from storage, compiling kernels…
Entities: NVIDIA